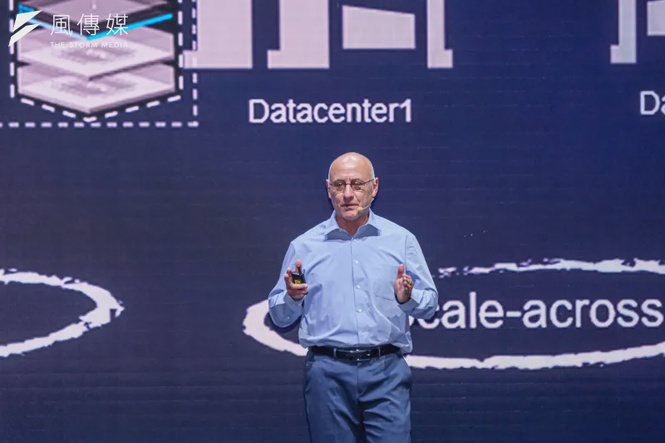
At the SEMICON Taiwan 2026 CEO Summit on September 2, Broadcom (NASDAQ: AVGO) executive Asad Khamisy declared that AI networks are no longer peripheral infrastructure — they have become the compute itself.
Speaking to an audience of chip industry leaders at Taipei's Nangang Exhibition Center, Khamisy — senior vice president and general manager of Broadcom's Core Switching Business Unit — laid out a stark contrast: traditional cloud networks run at roughly 60% utilization, while AI networks have already crossed 90%.
The difference, he argued, is structural. Cloud computing disperses unrelated workloads across servers that can tolerate waiting their turn. AI training is categorically different: thousands of GPUs are chained together on a single task, and any network delay or dropped packet forces every accelerator to stall while waiting for missing data to arrive.
Simulation of 576 GPUs Reveals Network as the Bottleneck
To make the point concrete, Broadcom modeled a 400-billion-parameter FP16 model distributed across 576 GPUs. As tensor parallelism increases, each GPU handles less computation per step — but communication overhead climbs in lockstep. Beyond a certain threshold, adding more GPUs yields diminishing returns: gains from additional processing power are canceled out by the time spent waiting for data to traverse the network.
"In the cloud, we see network utilization around 60%," Khamisy said. "In AI environments, it's already above 90%." At those saturation levels, the margin for congestion, retransmission, and packet loss shrinks to near zero. Traffic engineering and fault recovery, he argued, are no longer afterthoughts — they determine how much useful compute a cluster can deliver per dollar spent.
Three-Tier Ethernet Architecture Spans Rack to Campus
Broadcom's answer is a unified three-tier Ethernet architecture designed to scale from a single rack all the way to multi-building AI campuses.
The first tier — Scale-up — handles GPU-to-GPU communication within a single rack, where packets are short and latency must be measured in nanoseconds. The second tier, Scale-out, links multiple racks within a building using Clos or Fat-tree topologies capable of reaching roughly 100,000 GPUs. The third tier, Scale-across, addresses the reality that power constraints will push AI compute across multiple buildings or geographically separate campuses.
Broadcom has a chip for each tier. The Tomahawk Ultra targets Scale-up traffic, delivering roughly 250 nanoseconds of latency on 64-byte packets. The Tomahawk 6 spans both Scale-up and Scale-out with 102.4 terabits per second of switching capacity — configurable with 512 ports at 200G or 1,024 ports at 100G. The Jericho 4 handles Scale-across duties with deep buffering, line-rate encryption, and traffic engineering for cross-building and cross-region links.
The case for a unified Ethernet stack across all three tiers, Khamisy said, comes down to operational simplicity: shared management tools, a common software stack, and the flexibility to reallocate interfaces and accelerator resources as workloads shift.
"The network is the computer," he concluded, "and Ethernet is the way to build this network end-to-end." As AI clusters expand from thousands of accelerators to hundreds of thousands — or eventually millions — the network stops being supporting infrastructure and becomes the architecture of AI itself.
In Full
SEMICON Taiwan 2026 | Broadcom: Without Smarter Networks, More GPUs Won't Save Your AI Cluster
Original Article In Chinese